At the "Building the Agentic AI Infrastructure" event I shared the one question every team building AI agents eventually has to answer: when do you run inference locally and when do you pay for cloud inference?
The event was hosted by Lionel Sim @ The AI Capitol in partnership with Bitdeer AI and the SMU Artificial Intelligence Club (SMUAI). It pulls together the two layers of the AI stack that rarely share a room: the people building agents and the people running the compute and infrastructure underneath them.
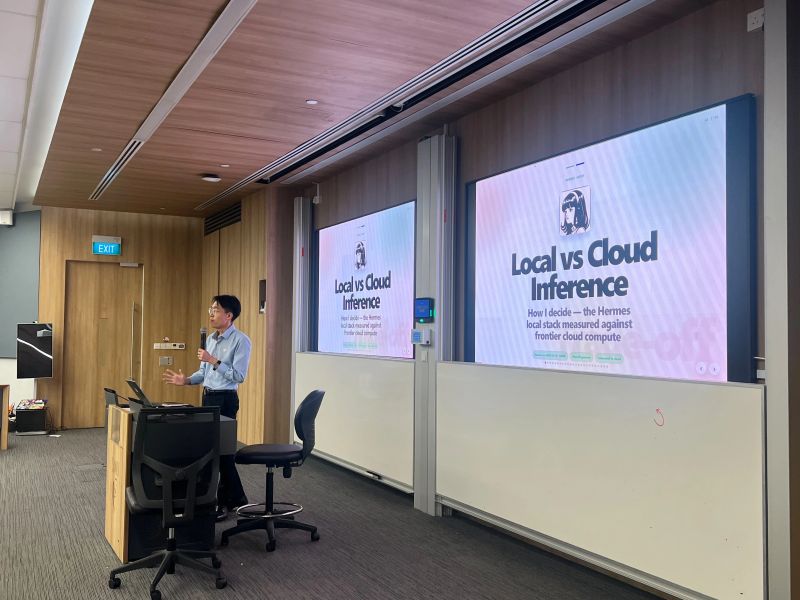
Here was what I shared from my own privacy-first Hermes Agent build:
- An ASUS GX10 with 128GB unified memory running Qwen3.6 35B fully offline, managed by a local gateway.
- Why local wins: data sovereignty, zero marginal token cost, no vendor lock-in.
- Why the cloud still wins: trillion-parameter frontier models, speed, large context window.
- The real trade-off is cost versus capability.
- Live demos showing Hermes Agent redacting a finance document so nothing leaves the machine. I also showed a same-prompt coding test pitching a locally run 35-billion model against a 2.8-trillion model. The obvious winner was Kimi K3 running on Bitdeer AI, at a cost of less than $0.001 to build a really simple personal finance tracker.
The practical takeaway for teams: run the sensitive, high-volume, repetitive work locally where the marginal token cost is zero and the data never leaves your control, and reserve paid frontier inference for the small number of tasks where raw capability actually decides the outcome. Build the routing layer once and you can swap models underneath it as the market moves.